microGPT
A GPT written from scratch in PyTorch: 82M parameters, designed to be trained on a consumer GPU (RTX 4060, 8 GB).
- Tokenizer, model, training, sampling
- Solo
- Personal project
133 GitHub stars, 19 forks (October 2026) - Python, PyTorch, Hugging Face Tokenizers, Weights & Biases, Streamlit
What it is
A small, readable GPT that trains on one consumer GPU.
What I built
All of it: tokenizer, dataset preparation, model, training loop, sampling and a Streamlit app for inference.
Technical notes
- 8 layers, 8 heads, 768-dimensional embeddings, a 512-token context. 82M parameters.
- A byte-level BPE tokenizer with a 16,384-token vocabulary, trained on MiniPile (about 6 GB of text).
- Pre-LayerNorm blocks; causal attention through PyTorch’s scaled_dot_product_attention, with a triangular-mask fallback.
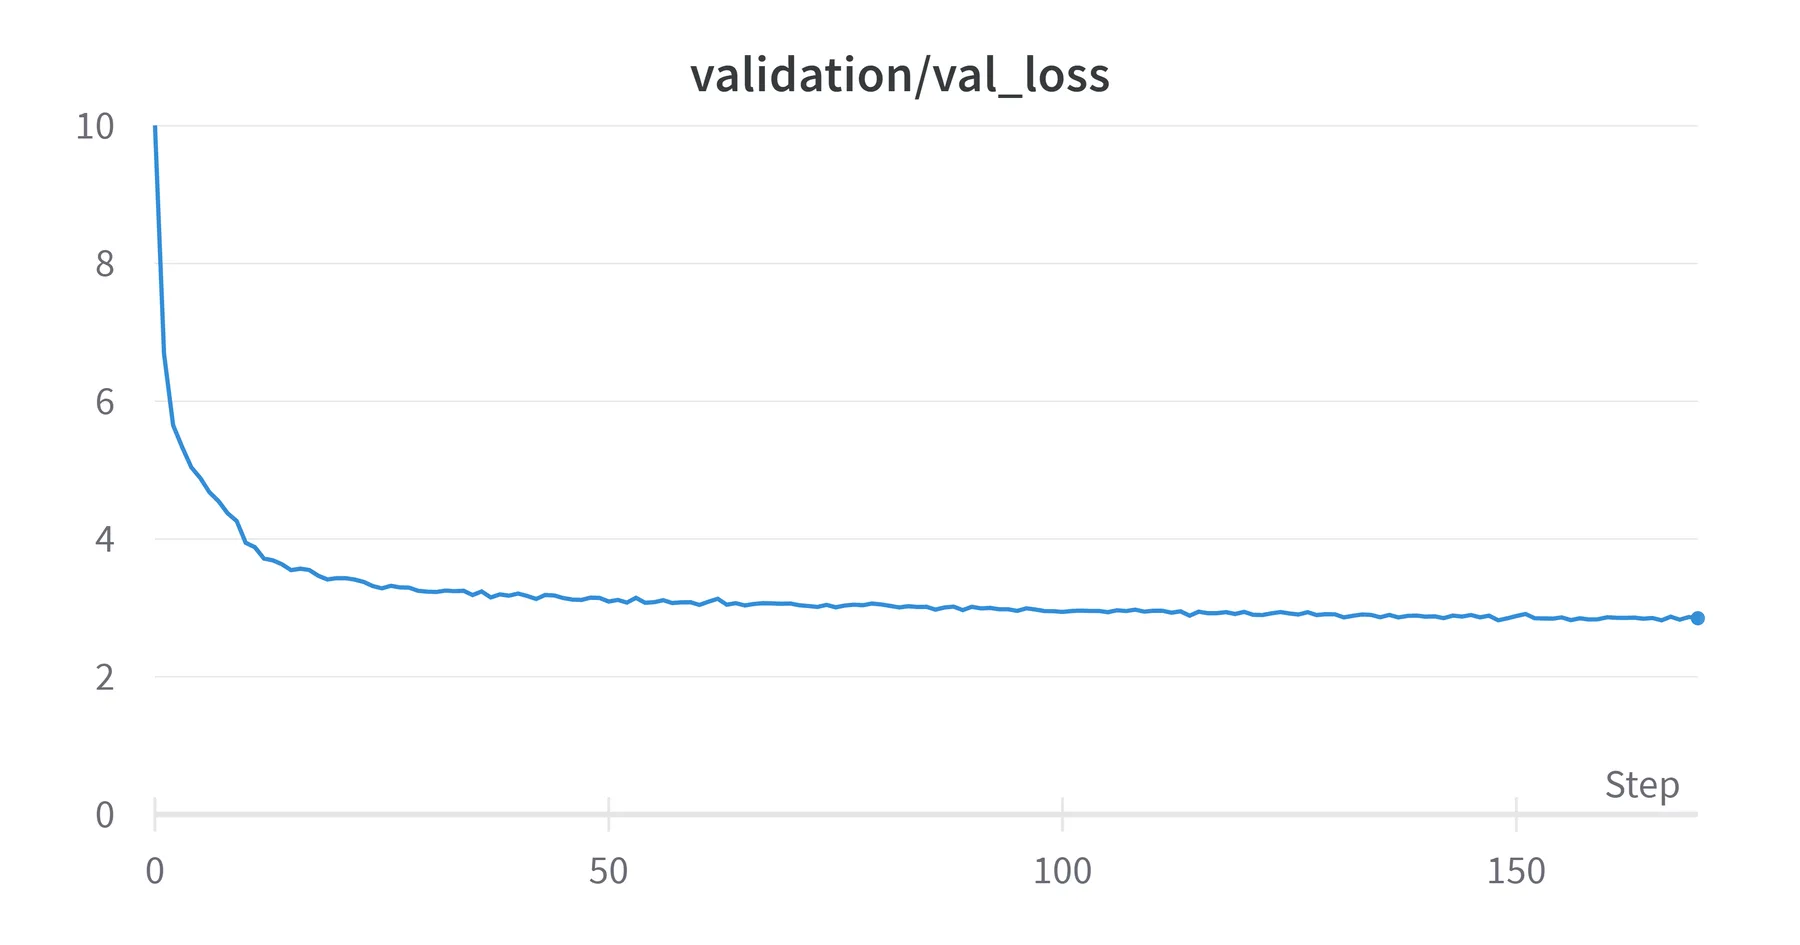
- Learning rate 6e-4, batch size 12, gradient clipping at 1.0, cosine schedule with 2,000 warm-up steps.
- Sampling with top-k, top-p and temperature.
Parameter count
82,255,360parameters, about 82.3M.
| Component | Arithmetic | Parameters |
|---|---|---|
| Token embedding16,384 × 768 | 16,384 × 768 | 12,582,91215.3% |
| Position embedding512 × 768 | 512 × 768 | 393,2160.5% |
| Attention q, k, vno bias8 × 768 × 2,304 | 8 × 768 × 2,304 | 14,155,77617.2% |
| Attention outno bias8 × 768 × 768 | 8 × 768 × 768 | 4,718,5925.7% |
| MLP up8 × (768 × 3,072 + 3,072) | 8 × (768 × 3,072 + 3,072) | 18,898,94423.0% |
| MLP down8 × (3,072 × 768 + 768) | 8 × (3,072 × 768 + 768) | 18,880,51223.0% |
| LayerNorms in blocks8 × 2 × (768 + 768) | 8 × 2 × (768 + 768) | 24,5760.030% |
| Final LayerNorm768 + 768 | 768 + 768 | 1,5360.002% |
| Output headnot tied768 × 16,384 + 16,384 | 768 × 16,384 + 16,384 | 12,599,29615.3% |
| Totalone block 7,084,800, × 8 | one block 7,084,800, × 8 | 82,255,360 |
- From
config.json(8 layers, 8 heads, 768 wide, 512-token context, 16,384-token vocabulary) andgpt.pyat c031e14. The head is its own linear layer with a bias, not tied to the token embedding. - Cross-check: PyTorch counts 82,255,360 when
gpt.GPTis built with this config.